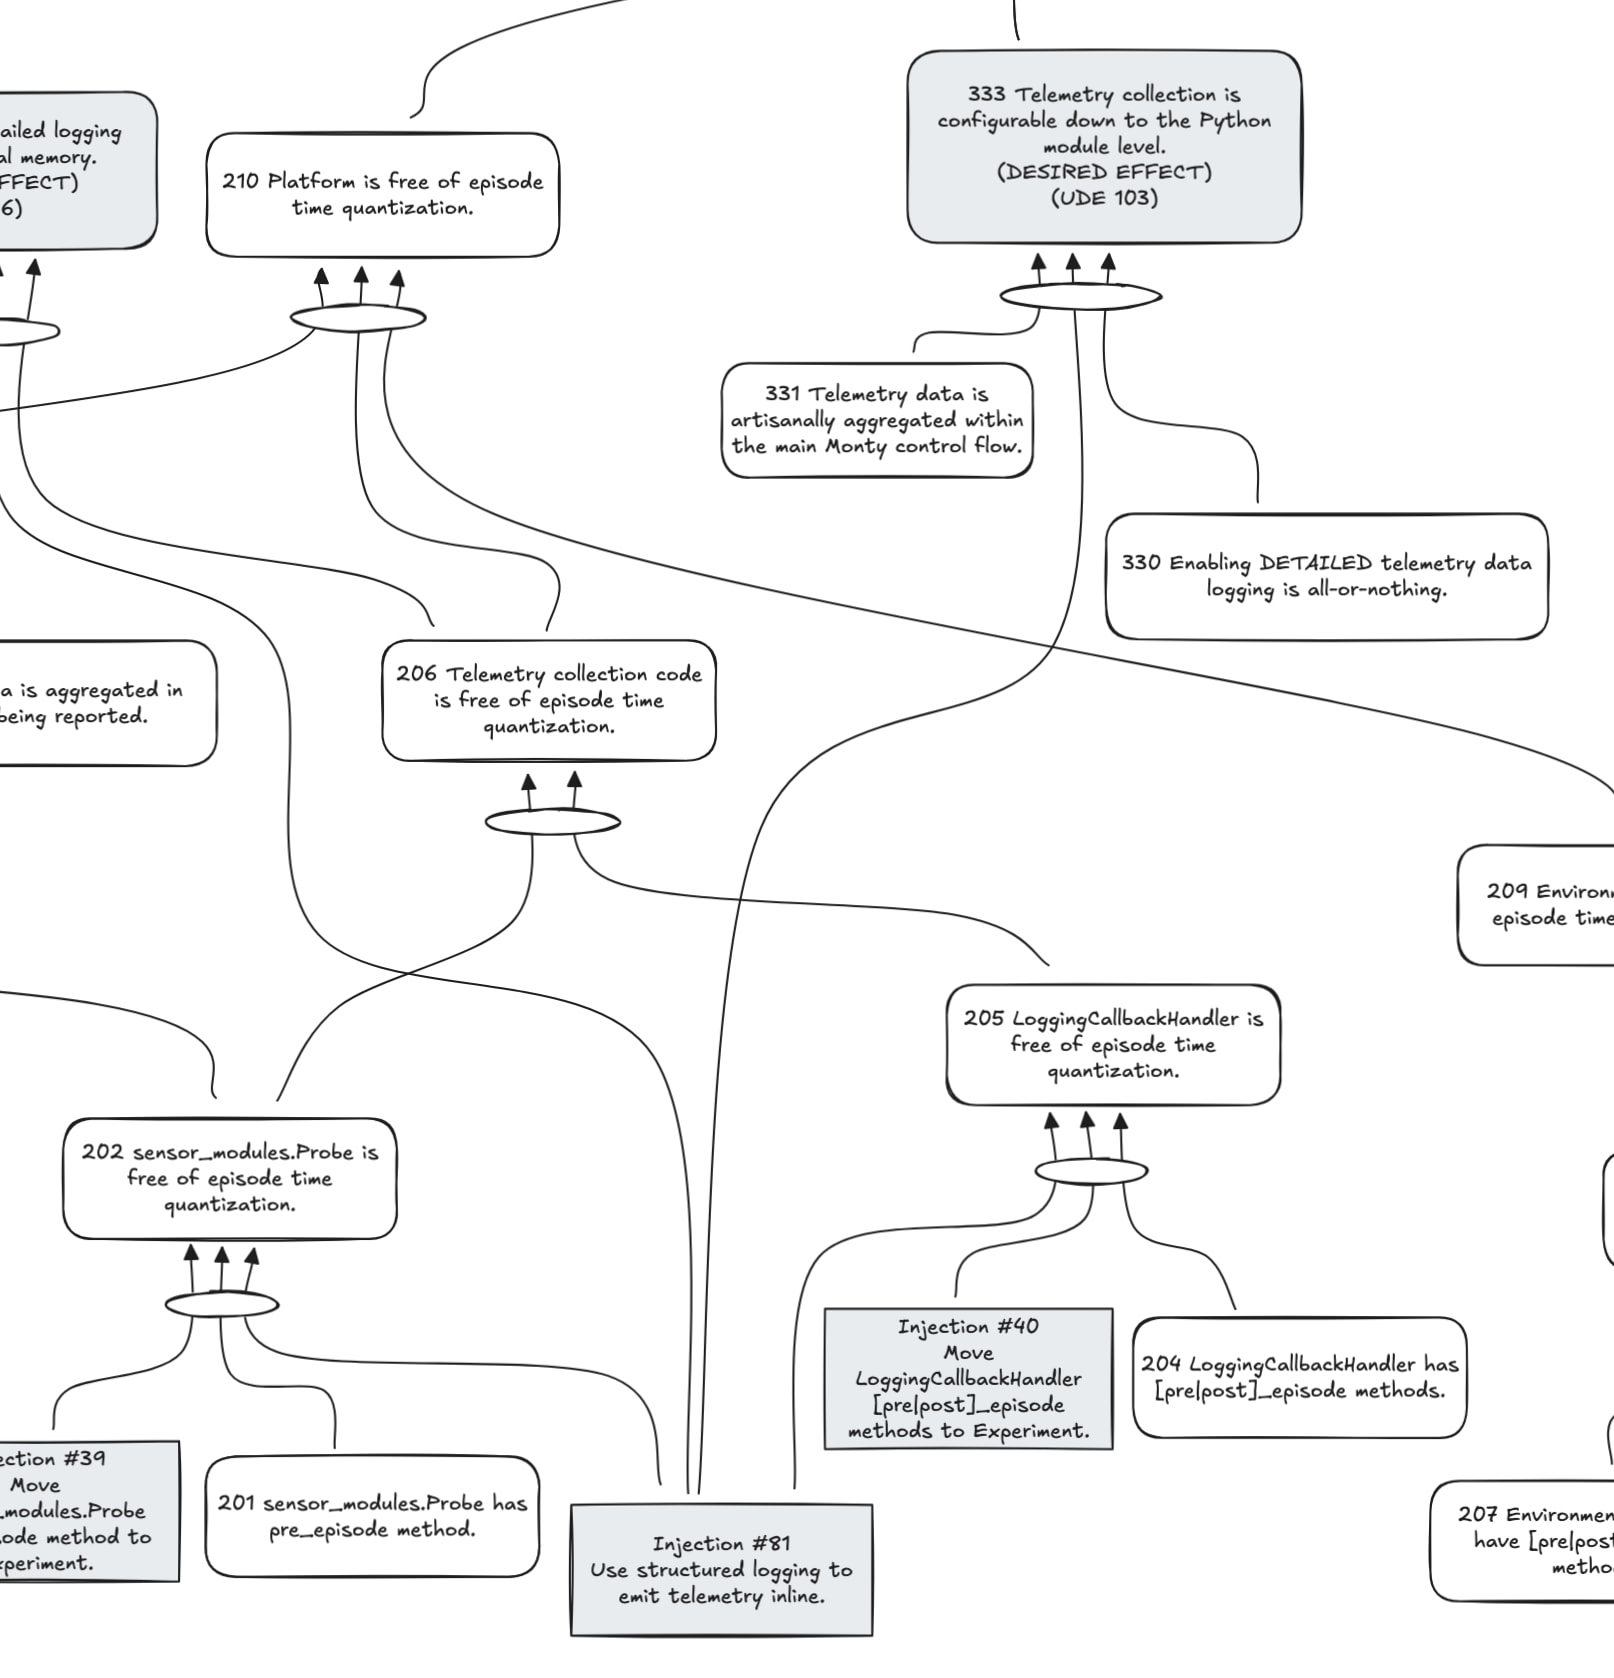
333 Telemetry collection is configurable down to the Python module level

Leading to it is (Injection #81 Use structured logging to emit telemetry inline).

This is a large project. Basically, the goal is to replace our custom logging framework for all the scientific data with a logging-like telemetry pipeline that emits snapshot events. Essentially, replacing tbp.monty/src/tbp/monty/frameworks/loggers/graph_matching_loggers.py at main · thousandbrainsproject/tbp.monty · GitHub and everything that interacts with it. That is, no longer collecting data at hardcoded step, episode, or epoch boundaries, but instead emit them inline with appropriate event metadata so that any application reading the telemetry snapshot stream can construct whatever it needs for data analysis/visualization purposes.

The Current Reality Tree Undesirable Effect (103 Platform internal representations are difficult to visualize) contains more context on the problem we are running into.

I have only thought through the design of this at a very high level. Essentially, what I’m thinking is something analogous to the logger interface, but for telemetry.

So, where we have logger:

logger = logging.getLogger(__name__)

# ...

logger.error(...)
logger.warn(...)
logger.info(...)
logger.debug(...)

We would have an analogous pipeline (using logging as the implementation detail) that would emit telemetry events:

telemetry = monty.getTelemetry(__name__)

# ...

telemetry.snapshot(...) # some scientific data

This way, we could reuse all the existing logging infrastructure to select, handle, and filter scientific data emitted by the application.

Aside from the emit side of things, this project also requires rethinking and redoing all of the live and offline visualizations.

This is a large topic. I think we’ll need an RFC to keep everyone on the same page. Before we start going through all the details, I want to see if this is of interest first.

Regarding the splitting of the work. I’m not yet sure if it can be split up. However, if we were to try…

One constraint on what we’d merge into tbp.monty is that we do not want to include dead code. So, practically speaking, if there’s a PR with an unused class, I think it is very unlikely to get merged.

If the work were split, I think we might end up needing to add new telemetry without removing the old way. This can then be done in parts. For example, all learning modules now (also) emit telemetry in a new way. All sensor modules, environments, habitat, mujoco.. I’m not sure what the best way of breaking it up will be, but there’s probably something that will make sense. However, always adding a full implementation to a portion of Monty, as opposed to a partial implementation to none of Monty.

The reason I think we might want to emit both telemetry types is that tools rely on the current way telemetry is aggregated. Even with all the new telemetry in place, there is a tail of tools that would need to be updated. Only once those tools are updated (to be enumerated), would we then fully transition to the new telemetry.

3 Likes

I started hacking something together; work in progress, needs more refining, not functional yet.

Calling for example telemetry.snapshot(logging.INFO, event) forwards the event as a LogRecord with the TelemetryEvent instance stuffed into the record’s extra dict. A QueueHandler attached to that logger puts the record onto a process-level queue.Queue without blocking the emitting thread.

On the other side, a QueueListener drains that queue on a single background thread and fans out each record to its registered handlers. One of those handlers is a TelemetryBroker, which maintains a dict of subscriber queues keyed by schema_id. For each incoming record it puts the event onto whichever consumer queues have subscribed to that schema. Other handlers (plotter, disk save, out-of-band dispatcher, etc.) receive the same record independently.

A consumer calls broker.subscribe("monty.some.schema_id") which returns a queue.Queue. It drains that queue however suits it, whether synchronously at a checkpoint, or on its own thread blocking on q.get(). Level filtering inherited from logging means a handler or consumer can ignore everything below a chosen level without any change to emitting code.

@dataclass
class TelemetryEvent:
    """Base for all telemetry snapshot events."""
    schema_id: ClassVar[str]
    schema_version: ClassVar[int] = 1

    emitter: str  # __name__ of the emitting module
    timestamp: float = field(default_factory=time.monotonic)
    episode: int
    step: int
    mode: str = "eval"  # "train" / "eval"

@dataclass
class EpisodeStepEvent(TelemetryEvent):
    """Example event for `MontyExperiment.env_interface.step`."""
    schema_id = "monty.env_interface.step"
    observations: Observations
    state: ProprioceptiveState

class Telemetry:
    def __init__(self, logger: logging.Logger):
        self._logger = logger

    def snapshot(self, level: int, event: TelemetryEvent):
        """Emit a structured telemetry event at the specified level.

        Args:
            level: logging level (logging.DEBUG, logging.INFO, etc.)
            event: The TelemetryEvent dataclass instance.
        """
        self._logger.log(
            level,
            event.schema_id,  # msg is the schema id for text sinks
            extra={"telemetry_event": event},
            stacklevel=2,  # reports the stack frame that called `snapshot()`
        )

class TelemetryBroker:
    """Sits between QueueListener and consumers.

    Registered as a handler with QueueListener. Fans out each event to whichever
    consumer queues have subscribed to that schema_id.
    """

    def __init__(self):
        self._lock = threading.Lock()
        self._subscriptions: dict[str, list[queue.Queue]] = defaultdict(list)

    def subscribe(self, schema_id: str, maxsize: int = 0) -> queue.Queue:
        """Returns a queue that will receive all events matching schema_id."""
        q = queue.Queue(maxsize=maxsize)
        with self._lock:
            self._subscriptions[schema_id].append(q)
        return q

    def unsubscribe(self, schema_id: str, q: queue.Queue):
        with self._lock:
            self._subscriptions[schema_id].remove(q)

    def emit(self, record: logging.LogRecord) -> None:
        event = record.__dict__.get("telemetry_event")
        if event is None:
            return
        with self._lock:
            queues = list(self._subscriptions.get(event.schema_id, []))
        for q in queues:
            try:
                q.put_nowait(event)
            except queue.Full:
                pass  # drop or log; don't block the listener thread

    def handle(self, record: logging.LogRecord):
        self.emit(record)

    # QueueListener expects a logging.Handler-like object
    def createLock(self):
        pass

    def acquire(self):
        pass

    def release(self):
        pass

#--------------------------------------------------------------------------------------

class MontyBase(Monty):
    [...]

    def __init__(
        [...]
    ):
        [...]
        self.broker = TelemetryBroker()
        self._telemetry_queue: queue.Queue
        self._telemetry_listener: QueueListener
        self._configure_telemetry(handlers=[self.broker])

    def _configure_telemetry(self, handlers: Sequence[logging.Handler]):
        _telemetry_queue = queue.Queue()  # TODO: maxsize?

        # QueueListener fans out to real handlers on its own thread
        self._telemetry_listener = QueueListener(
            _telemetry_queue,
            *handlers,
            respect_handler_level=True,  # abide by each handler's own level filter
        )
        self._telemetry_listener.start()

    def _shutdown_telemetry():
        if _telemetry_listener is not None:
            _telemetry_listener.stop()
        # Unblock any consumers waiting on q.get()
        for queues in broker._subscriptions.values():
            for q in queues:
                q.put(None)

    def getTelemetry(self, name: str) -> Telemetry:
        logger = logging.getLogger(f"telemetry.{name}")
        if not logger.handlers:
            if self._telemetry_queue is None:
                raise RuntimeError(
                    "configure_telemetry() must be called before getTelemetry()"
                )
            logger.addHandler(logging.handlers.QueueHandler(self._telemetry_queue))
            logger.setLevel(logging.DEBUG)  # default val, overridden by handler
            logger.propagate = False
        return Telemetry(logger)

#--------------------------------------------------------------------------------------

# Example of consumer running on its own thread (doesn't compile, just a quick example)
def live_plotter_consumer(q: queue.Queue) -> None:
    while True:
        event: EpisodeStepEvent = q.get()  # blocks until an event arrives
        if event is None:  # sentinel for shutdown
            break
        live_plotter.show_observations(
            *live_plotter.hardcoded_assumptions(event.observations, model),
            event.step
        )

env_step_q = broker.subscribe("monty.env_interface.step")
threading.Thread(target=live_plotter_consumer, args=(env_step_q,), daemon=True).start()
3 Likes

Very nice. The overall approach looks great. I’m sure I’ll pick at some details in PRs, but the shape of things looks good. Thank you for putting this together.

A follow-up thought… one of the things that might take some time is designing events and how to reassemble them into all the visualizations we currently have. I wonder if there is a shim that would fit into the telemetry infrastructure you’re setting up that could do the aggregation of telemetry like currently being done in post_episode logger stuff in tbp.monty/src/tbp/monty/frameworks/loggers/graph_matching_loggers.py at 7f242b532be9fac1dc9adf7967eed8f85616a905 · thousandbrainsproject/tbp.monty · GitHub . This would be somewhat like what you demonstrated with the live plotter code. I’m thinking there’d be some “legacy” handler and the experiment could call post_episode (which eventually ends up calling log_episode/report_episode and such), and it would output what the current monty_handlers.py and wandb_handlers.py output. Does that make sense? I wouldn’t worry about it right now, but it’s something to consider after you feel you’ve got the telemetry setup the way you like it.

First, congratulations! Next, of course, some quibbles…

The word [Tt]elemetry is quite overloaded. Even in the context of software systems, it can refer to a general approach or to specific packages. For example, in the Elixir world, it commonly means either the telemetry or the opentelemetry-erlang library:

Telemetry is a lightweight library for dynamic dispatching of events, with a focus on metrics and instrumentation. Any Erlang or Elixir library can use telemetry to emit events. Application code and other libraries can then hook into those events and run custom handlers.

Note: this library is agnostic to tooling and therefore is not directly related to OpenTelemetry. For OpenTelemetry in the Erlang VM, see opentelemetry-erlang, and check opentelemetry_telemetry to connect both libraries.

FWIW, I suspect that the Cloud Native Computing Foundation (CNCF)'s OpenTelemetry system is going to be the Golden Path for this sort of thing. Basically, it checks all the usual boxes for licensing, industry buy-in, etc. (:-):

OpenTelemetry is an open source observability framework for cloud native software. It provides a single set of APIs, libraries, agents, and collector services to capture distributed traces and metrics from your application.

OpenTelemetry is an open source observability framework created when CNCF merged the OpenTracing and OpenCensus projects. OpenTracing offers “consistent, expressive, vendor-neutral APIs for popular platforms” while the Google-created OpenCensus project acts as a “collection of language-specific libraries for instrumenting an application, collecting stats (metrics), and exporting data to a supported backend.” Under OpenTelemetry, the projects create a “complete telemetry system [that is] suitable for monitoring microservices and other types of modern, distributed systems — and [is] compatible with most major OSS and commercial backends.” It is the “second most active” CNCF project. In October 2020, AWS announced the public preview of its distro for OpenTelemetry.

OpenTelemetry has a number of useful-sounding affordances, including access to the Prometheus suite. As the Goog puts it:

Prometheus is an open-source systems and service monitoring system that collects and stores metrics as time-series data, specializing in multi-dimensional data models and high-performance querying (PromQL). It commonly monitors Kubernetes and microservices using a pull model via HTTP, scraping metrics from targets to enable powerful alerting and dashboarding.

Wikipedia sez:

Prometheus is a free software application for event monitoring and alerting. It records metrics in a time series database built using an HTTP pull model, supporting high dimensionality through key-value label pairs, flexible queries, and real-time alerting. The project is written in Go and licensed under the Apache 2.0 License, with source code available on GitHub.

Please consider making OpenTelemetry a supported target for Monty’s nascent telemetry offerings. For extra credit, provide a way to access and/or request the telemetry via the Model Context_Protocol (MCP). And a pony…

The discussed system is for internal Monty comms with native Python types, whereas OTel is for publishing standardized serialized data to the outside world. Different use cases :wink: One could write an OpenTelemetryHandler(logging.Handler) class to connect these internals to OTel via e.g. self._configure_telemetry(handlers=[self.broker, OpenTelemetryHandler()]), should the need arise.

Definitely, I suppose visualizations would likely need their own threading.Thread, so they can block while waiting telemetry events. I’ll try a couple different approaches with the live plotter to see what feels right.

Yeah I’ve been looking at that as well, but I haven’t settled yet. I was kinda thinking about a step aggregator handler that would subscribe to step-level telemetry, then emit episode-level telemetry, which could itself be aggregated by an experiment-level handler, which could then be emitted out to monty_handlers-like and wandb_handlers-like consumers. Something along those lines. But first I wanna dial in the telemetry core using live plotter as the lab rat.

3 Likes

A little progress report; I put together a telemetry core prototype, managed to get it working with the live plotter for observations and proprioceptive state:

Tested it with

python run.py experiment=base_config_10distinctobj_dist_agent experiment.config.show_sensor_output=true

I initially wanted to run the plotter in a separate thread, but turns out matplotlib and Habitat both hate running in a thread, so right now it’s not threaded. The snapshot is emitted after MontyObjectRecognitionExperiment.env_interface.step then the live plotter consumes the snapshot in a blocking manner on the main thread.

I created ThreadedTelemetryConsumer and MultiprocessTelemetryConsumer classes as part of my shenanigans, I think the plotter could eventually live in its own multiprocessing.Process, but further data separation is needed, as to keep pickling down to a minimum.

MultiprocessTelemetryConsumer is itself a ThreadedTelemetryConsumer, its thread pickles incoming events and sends them to the mp.Process.

Will keep at it

3 Likes

Sounds like good progress @AgentRev.

I want to highlight that getting the live plotter to work is a nice demonstration of telemetry working, but keep in mind that the telemetry change is distinct from converting the live plotter to consume the telemetry format.

For example, it may be more useful to use “off-the-shelf” technology like https://rerun.io/ rather than continuing with custom visualizations.

Yeah I was just using the plotter as a convenient guinea pig, before moving on to graph matching loggers.

1 Like

This is more for context and to share what I think are the types of systems that Monty telemetry will hand off data to.

1 Like

Nice!

One thing I’ve wondered about is control signals going in the other directions. More specifically, it’d be cool if the live plotter could control the execution rate, pause, step by one, etc.

I briefly played around with using ZeroMQ to handle the pub/sub system over TCP sockets. My receiving process ran a pyqt app that listened for messages on a QThread, which then handed messages back to the main thread for visualization. The nice thing about that setup was that the listening process could run in an environment without tbp.monty, so it wasn’t constrained to Jurassic Python versions or old libraries. The downside was having to serialize/deserialize Monty structures that the receiving process didn’t know anything about. I figured there might be a way to share a schema or something, but I didn’t get that far.

Note that I only used ZeroMQ and PyQt because of familiarity. I’ve no idea if there are vastly superior choices on the message passing side. Lots of cool visualization options for PyQt.

1 Like

@tslominski Rerun seems great! I had heard of Foxglove before which is similar, but they are more enterprise/fleet-oriented, whereas Rerun is more user-centric and OSS-friendly. They have some pretty neat live web demos, like this RGBD example, source code even included:

@sknudstrup Interesting, I did something along those lines almost a decade ago, an interactive telemetry visualizer for my university rocketry club: https://github.com/AgentRev/GyroLog We wound up a couple miles of optical fiber to make a laser gyroscope, and data was broadcast via a radio transmitter. It could also replay data from a CSV file. Main thread was in charge of GUI, and a QThread streamed the radio transmitter or CSV file in real-time.

gyrolog

Although, if I was to redo it today, I’m not sure I would use Qt, I would probably go with vedo like Ramy did with tbp.plot. So, it is feasible to have a plotter consumer accumulate timestamped data in a list and allow real-time rewind / fast-forward à la YouTube Live, and have plotter buttons literally control Monty execution flow, indeed.

In fact, a telemetry consumer could technically be used for flexible cross-thread procedure calling; i.e. execute X method if Y event schema is received, using its contents as args, without having to shotgun queue.Queue instances over the place. However, at that point, maybe Pykka would be more adequate.

1 Like

Alright, another update.

I have a working telemetry implementation of all the BasicGraphMatchingLogger logic:

Operating principles:

  1. MontyExperiment.init_monty_data_loggers() creates a TelemetryEmitter("experiment", level=logging.INFO) and a PostEpisodeTelemetryConsumer.

  2. MontyExperiment.post_episode() snapshots a PostEpisodeTelemetry constructed from data extracted from MontyExperiment.logger_args and MontyExperiment.model. This part is roughly equivalent to the first half of BasicGraphMatchingLogger.update_episode_data().

  3. The snapshot is routed via logging.Logger.log() thru TelemetryBroker to PostEpisodeTelemetryConsumer, which implements all the remaining logic of BasicGraphMatchingLogger.

  4. The consumer does the handler.report_episode() loop, which successfully sends the aggregated self.data to Wandb. It also snapshots self.data into a ExperimentStatsTelemetry event, which can be captured Monty-wide by yet-to-be-implemented consumers.

Notes:

  • I have done some minor tweaks to my initial telemetry core from last month. The most noteworthy change is the removal of all telemetry code from MontyBase. It is now self-contained inside TelemetryEmitter (previously named Telemetry) and thus available Monty-wide. Its constructor is equivalent to the prior get_telemetry, and also performs what _configure_telemetry() did; the TelemetryBroker is inside of it as a global class variable.

    I amended my commit history to remove my live plotter stuff and ensure the telemetry core changes are properly diffed in the above WIP commit.

  • The handler.report_episode() loop could optionally be moved to its own separate consumer.

  • I have not yet touched anything related to DetailedGraphMatchingLogger or SelectiveEvidenceLogger. I wanted to first validate the initial approach with the team before I tackle those.

  • Snapshots do not carry any dynamic objects like MontyBase, MontyExperiment, LearningModule, and so on; only primitive types (and dicts of them) extracted upon snapshot. Ideally, I want to avoid snapshotting dynamic objects, since a consumer might process an event any arbitrary amount of time after the snapshot, meaning those objects might already have changed state, e.g. moved on to the next episode. This will have to be kept in mind upon porting the other graph loggers.

  • I have not yet altered the legacy BasicGraphMatchingLogger, besides commenting out the handler.report_episode() loop. I wanted to temporarily leave it functional to validate that its output and the telemetry output are identical, and minimize the diff size for proof-of-concept review.

  • I have also not touched Hydra configs yet, again for matters of simplicity while validating the proof of concept, but this will be easy to sort out once the rest is dialed in.


Pardon the month-long delay, I got tangled up in crunch time and gardening. The local deer herd keeps wreaking havoc on my poor seedlings…

4 Likes

Thank you for the update @AgentRev ! Great to see progress… I hear deer can become pests real quick!

I’m looking forward to running this to see what I get. I didn’t have time to fully review everything today. However, I can offer some high-level overview comments…


I see telemetry nested under tbp.monty.frameworks.loggers.telemetry. I’m only highlighting this because perhaps we are not seeing the relationship between telemetry and loggers the same way. I view telemetry as a peer of normal logging, and a replacement for “loggers”. In code, the way that I would surface that would be by putting telemetry in tbp.monty.telemetry. The “frameworks” organizational structure is deprecated and we’ll move out of it eventually. Or in tbp.monty.frameworks.telemetry if you don’t want to skip steps :slight_smile: . A peer relationship.

In a similar vein, I see

        # TODO telemetry: separate config for log level
        self.telemetry = TelemetryEmitter("experiment", level=logging.INFO)
        self.post_episode_telemetry = PostEpisodeTelemetryConsumer(
            level=logging.INFO, handlers=monty_handlers, output_dir=self.output_dir
        )
        self.post_episode_telemetry.subscribe()

as part of MontyExperiment.init_monty_data_loggers(), again, sort of nesting it under “loggers.” I think it would be easier to compartmentalize telemetry from the beginning, even introducing MontyExperiment.init_telemetry() for now.


DISCLAIMER: I’m not sure I fully understand the approach. I will attempt to provide some feedback, but perhaps I misunderstood how things are wired. Is there an overall diagram that you maybe have that could give a high-level view of how everything is connected?

Here’s where I’m confused..

I see a self.telemetry.snapshot(...) inside of MontyExperiment.post_episode(), but the snapshot that is emitted uses self.logger_args.

I think what I’ve been attempting to describe differs. I think perhaps I can best demonstrate the difference by focusing on MontyExperiment.post_episode():

    def post_episode(self, steps):
        # ...

        self.telemetry.snapshot(
            level=logging.INFO,  # TODO telemetry: adjust log level
            event=PostEpisodeTelemetry.from_logger_args(
                logger_args=self.logger_args,
                model=self.model,
                emitter=self.__class__.__name__,
            ),
        )
        self.post_episode_telemetry.pump()  # consumes above snapshot

        # ...

I see here telemetry being collected at the episode boundary by introspecting Monty itself. What I expected to see instead was some sort of EpisodeTelemetryHandler that was subscribed to all telemetry events, and as each telemetry event was emitted by the code throughout Monty, it kept a running track of episode specific telemetry. Then, when post_episode() was called, something like self.episode_telemetry_handler.post_episode() gets called and this emits the equivalent of the above.

The main difference I am highlighting is that what I’ve been trying to describe is that PostEpisodeTelemetry event is being assembled step by step, event by event, by some sort of EpisodeTelemetryHandler, and when prompted by the experiment that the episode is over, this EpisodeTelemetryHandler flushes its internal state in form of the PostEpisodeTelemetry. The EpisodeTelemetryHandler.post_episode() is not the moment telemetry is gathered, that’s already been happening step by step, event by event. post_episode() only generates the PostEpisodeTelemetry from already gathered data.

Another way of saying this, the only input into creating PostEpisodeTelemetry would be the events emitted on the telemetry stream. So, the only way of creating a PostEpisodeTelemetry would be to listen in on the telemetry stream and read the data that we need to keep for the episode.

For example, one of the episode stats is episode/correct.

class EpisodeTelemetryHandler(logging.Handler):

    _episode_correct: int

    def __init__(self, ...) -> None:
        # ...
        self._episode_correct = 0

    # magical future Python version
    def _emit(self, record: logging.LogRecord) -> None:
        match record.msg:
            case LearningModuleTerminalState(terminal_state=terminal_state):
                if terminal_state == "match":
                    self._episode_correct = self._episode_correct + 1
                # ...

    # today's Python version, something like...
    def emit(self, record: logging.LogRecord) -> None:
        event = record.msg
        if getattr(event, "kind", None) == "LearningModuleTerminalState":
            terminal_state = event.terminal_state
            if terminal_state == "match":
                self._episode_correct = self._episode_correct + 1
            elif ...:
            # ...
       if ...:
       # ... 

    def post_episode(self) -> None:
        # TODO: emit the `PostEpisodeTelemetry` event
        # reset for next episode
        # ...
        self._episode_correct = 0

Now, instead of going through loggers and eventually calling get_graph_lm_episode_stats(LM) which sets "primary_performance", which eventually makes its way to the episode_correct count, the learning module itself is responsible for emitting the relevant telemetry. In this particular case, I think this (on first glance, I might be wrong, but the idea is to show the shape of my proposal) would be in GraphLM.update_terminal_condition(...):

    def update_terminal_condition(self):
        """Check if we have reached a terminal condition for this episode.

        Returns:
            Terminal state of the LM.
        """
        possible_matches = self.get_possible_matches()
        # no possible matches
        if len(possible_matches) == 0:
            self.set_individual_ts("no_match")
            if (
                self.buffer.get_num_observations_on_object() > 0
            ):  # lm has gotten input during episode
                self.buffer.stats["detected_location_rel_body"] = (
                    self.buffer.get_current_location(input_channel="first")
                )
        # 1 possible match
        elif (
            (
                self.buffer.get_num_observations_on_object() > 0
            )  # had observations on object
            and len(possible_matches) == 1  # We have it narrowed down to 1 object
        ):
            object_id = possible_matches[0]
            pose = self.get_unique_pose_if_available(object_id)
            if pose is None:  # No pose determined yet
                logger.info(f"Pose for {self.learning_module_id} not narrowed down yet")
            else:
                self.set_individual_ts("match")
                logger.info(f"{self.learning_module_id} recognized object {object_id}")
        # > 1 possible match
        else:
            logger.info(f"{self.learning_module_id} did not recognize an object yet.")
        return self.terminal_state

I would say that everywhere you see self.set_individual_ts(...) (ts stands for “terminal state”) is an event emission point for the learning module. For example, instead of, or perhaps in addition to:

    self.set_individual_ts("match")

It would be something like:

    telemetry.emit(
        level=telemetry.INFO
        event=LearningModuleTerminalState(
            kind="LearningModuleTerminalState",
            id=self.learning_module_id,
            terminal_state=TerminalState.MATCH
        )
    )

With this inline emission… now the implementation of def event(...) in EpisodeTelemetryHandler would find this event, and add it to it’s running tally.. and once experiment called EpisodeTelemetryHandler.post_episode(), then EpisodeTelemetryHandler would emit the PostEpisodeTelemetry, which would show up on the telemetry stream after all the previous events. It is important to note that EpisodeTelemetryHandler does not prevent the propagation of telemetry events. However, it is an additional consumer of telemetry stream and keeps a running tally so that it can emit PostEpisodeTelemetry when told to do so.

I gotta run today, sorry. But I wanted to give you some initial comments in case you’ll get around to reading them before I have a chance to read through all of the code.

Thank you again!
2 Likes

(edit: This diagram is outdated) Here’s an overview of the system:

All the logging stuff is fully encapsulated. Consumers can subscribe to any number of event schema IDs, and be chained indefinitely, a little bit like your transformation pipeline RFC.

Yeah, I first created the files in loggers, then I simply corralled them in a telemetry subfolder mid-way. I didn’t think too much of it, I figured you’d suggest better.

That’s my plan, it’s the next step; I’m just getting the ball rolling. I’ve already started working on an episode aggregator (what you call EpisodeTelemetryHandler) to encapsulate the collection of logger_args. But then I thought, “Hang on, he said ‘replacing [graph_matching_loggers.py] and everything that interacts with it’, so I’ll start by migrating its code to a consumer and temporarily use post_episode() then we’ll adjust afterwards.” So, my MontyExperiment edits are not final.

The current version of PostEpisodeTelemetry is essentially the equivalent of what was being fed into graph_matching_loggers. graph_matching_loggers’s job is now performed by PostEpisodeTelemetryConsumer, which aggregates overall experiment stats at each episode boundary (upon reception of PostEpisodeTelemetry) and forwards it to Wandb (while also emitting ExperimentStatsTelemetry snapshots containing said data, for future use).

What you’re talking about is what’s happening one level earlier in the chain, i.e. the build-up of PostEpisodeTelemetry, which I haven’t touched in the WIP commit I posted earlier.

At the moment, my plan for implementing that is chained in the following fashion:

  1. Monty snapshots inline events (of a yet-to-be-made TelemetryEvent subclass) containing episode data, subscribable by any consumer.
  2. Those events are received and aggregated by a yet-to-be-made EpisodeTelemetryConsumer.
  3. Once the experiment reaches post_episode(), it signals EpisodeTelemetryConsumer to finalize and snapshot the results as a PostEpisodeTelemetry, subscribable by any consumer.
  4. PostEpisodeTelemetryConsumer consumes it, performs overall experiment aggregation, forwards them to MontyHandler objects (e.g. Wandb), and snapshots the results as a ExperimentStatsTelemetry, subscribable by any consumer.

Does that make sense? I think we’re following the same line of thought, just with slightly different semantics and methods.


As for the deer, well at least they are interesting coffee-break companions. :laughing:

On the topic of snapshots.

A snapshot is not intended to be “like a log(), but for telemetry()”. “Like a log(), but for telemetry” I would think would be log() or emit(). What I mean by “snapshot” is very specifically a fourth thing, outside the big three of (logs, metrics, traces) that don’t have a good industry standard name, but these are things like buffers, frames, snapshots, scrapes, etc.

This is why in my example above, I used telemetry.emit(...) and not telemetry.snapshot(...), because it is a telemetry event being emitted and not what meets the definition of snapshot:

telemetry.emit(
        level=telemetry.INFO
        event=LearningModuleTerminalState(
            kind="LearningModuleTerminalState",
            id=self.learning_module_id,
            terminal_state=TerminalState.MATCH
        )
    )

For a snapshot, I think it’d be something like:

telemetry.snapshot(
    level=telemetry.TRACE,
    event=SensorRGBA(
        kind="SensorRGBA",
        id=self.sensor_module_id,
        image=observation["rgba"] # <-- this data field makes it
        # a snapshot instead of just another telemetry event
    )
)

# likely wrapped to avoid extra data work
if telemetry.isEnabledFor(telemetry.TRACE):
    telemetry.snapshot(
        level=telemetry.TRACE,
        event=SensorRGBA(
            kind="SensorRGBA",
            id=self.sensor_module_id,
            image=observation["rgba"]
        ) 
    )    

For something like a PostEpisodeTelemetry event, unless it has large data buffers in it, I would still classify it as an “event” (it’s just a big/“wide” one) and not as a “snapshot.”

Another heuristic for discriminating between “event” and “snapshot” would be that snapshots are always telemetry.TRACE level and probably contain binary or blob data.

1 Like

Right, my current TelemetryEvent is basically a snapshot dataclass / schema, so I should rename all my current usages of “Event” to “Snapshot” for clarity.

Yes, I saw that message at the beginning and I kept it in mind. So, my old TelemetryEvent would become TelemetrySnapshot, and a new TelemetryEvent would be the parent dataclass of your LearningModuleTerminalState above.

1 Like

I’m trying to understand the need for a custom pubsub framework. Granted, I haven’t attempted to write code for the telemetry implementation, so I am probably unaware of problems that would arise. But, since you’ve been working on it, could you help me out and highlight what ends up leading to custom pubsub?

My mental model has been anchored around the built-in logging flow.

Also, the logging cookbook highlights how to log from multiple threads, with multiple handlers and formaters, and logging to multiple destinations.

logging.Logger doesn’t know about schema IDs, it multicasts everything to its registrants, forcing every handler to check every incoming LogRecord for relevancy. Letting all handlers perform relevancy check one by one is a blocking operation. As the number of schemas and consumers grow, so would both the single-core overhead and multi-core idle time for every emit / snapshot. Since we need to squeeze out every CPU cycle we can from this thing, letting that slide would be unadvisable.

It can be mitigated with a QueueListener thread, but this makes LogRecord delivery asynchronous; if you call snapshot() immediately followed pump(), it might turn up empty because the QueueListener isn’t done yet, leading to undesirable side-effects. It could also be mitigated with multiple differently-named loggers, and registering only certain consumers under certain loggers, but then that would shift the nature of the problem from bottleneck to cephalalgia; “which logger X is needed to ensure schema Y is delivered to consumer Z?” Is creating one logger per schema acceptable? What about consumers that want multiple events and/or snapshots, do they juggle all these loggers?

Instead of that can of worms, the broker acts as a singleton handler shared by all telemetry-related loggers that knows which consumers wants which schema(s), allowing leaner unicast instead of multicast. It also allows us to keep track of which consumers and schemas are currently expected to exist across Monty, for free. Without a broker or some other way to keep track of this, you’d have to dig into the loggers and interrogate their handlers. Should the need arise, it can also serve as a system-wide interception point where any emitted schema can be inspected.

Perhaps “broker” isn’t the right word; “router” might be more appropriate.

1 Like

Telemetry does not need to know about schema IDs. The telemetry only needs to be configurable at the Python module level (which aligns with logging’s configurability), not at the level of each event schema.

What sort of relevance check do you have in mind that handlers would perform here? Are you describing the enabled for level and filtered checks?

Is this performance hit something you observed in the tbp.monty code base? Could you share an example where benchmarks are impacted by logging in this way?


Regarding the number of handlers. I’m not seeing them multiply significantly. Aside from the usual handlers that put things into different sinks (stdout, file, WandB, visualizer, etc.), an experiment might add maybe three more: episode, epoch, and overall? Are you thinking of a different scenario with many more handlers?

By “schema ID” I’m referring to what you call kind in your examples. My code currently denotes this as SCHEMA_ID in my dataclasses. This is what I put in logger.log()'s msg argument. “Relevancy check” is your match record.msg statement.

I haven’t observed a performance hit, it’s just my standard thinking process of shaving off cycles when possible. I assume a module could emit many different schemas, and I know Logger will call the emit() of every handler under it, that this is a blocking call during which the rest of the thread is idle, and that handlers only care about specific msg values. The broker is a lightweight class that shaves off cycles by filtering msg at the very start, only calling emit() of handlers that subscribed to that msg value. The rest of my rationale are mere nice-to-haves. Making the broker a singleton classvar was however probably unwarranted.

My day job is quite unforgiving about worst-case scenarios, so maybe I am overthinking it too. If you conclude that the broker is unnecessary, I don’t mind at all axing it and turning the consumers into handlers directly.

Side-question; you wrote the message below earlier this year, is snapshots.{__name__} still on your mind?